Share
Cloud infrastructure for AI compute and inference. Provides NVIDIA GPU clusters and autoscaling to deploy models and agents in production.
What is GMI Cloud?
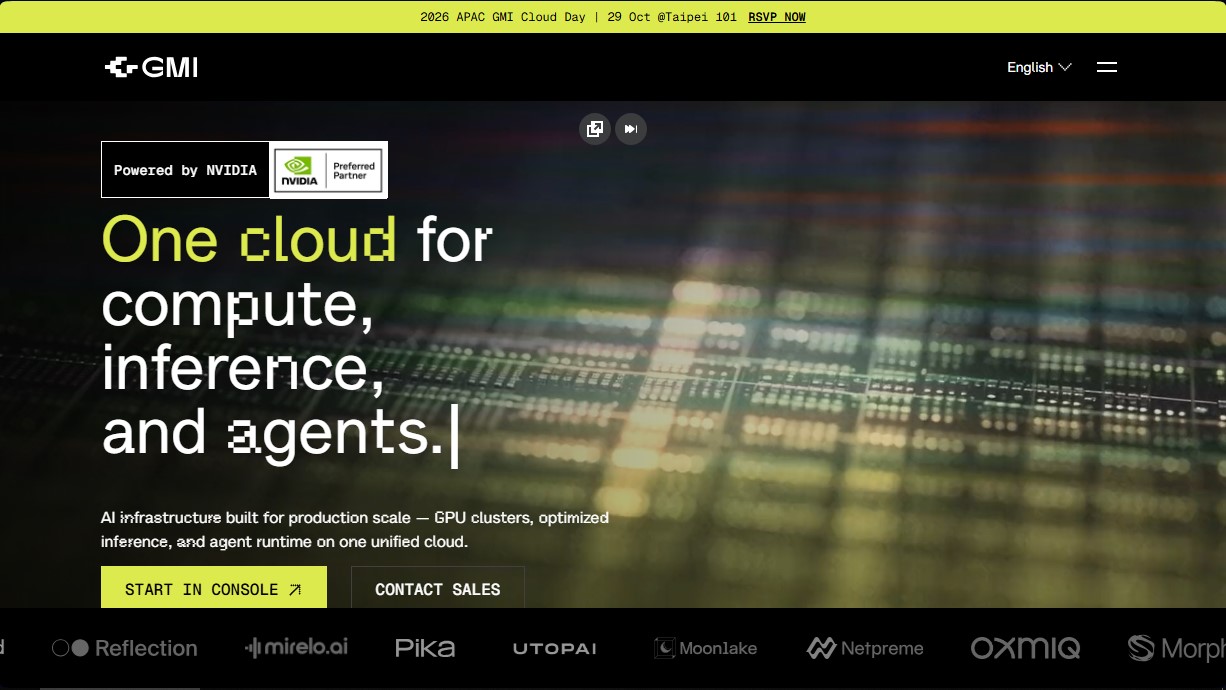
GMI Cloud is an AI infrastructure platform specifically designed for the deployment, inference, and management of agents in production environments. As a preferred NVIDIA partner, this solution unifies access to high-performance GPU clusters and optimized runtimes into a single cloud, enabling companies and developers to manage AI workloads at scale without the complexities of traditional architecture.
The tool operates with a serverless inference by default approach, allowing AI models to be executed instantly. Its technology enables auto-scaling to zero, eliminating idle costs and optimizing resource usage through integrated batch processing and latency-aware scheduling. For projects requiring total control, GMI Cloud facilitates the transition to dedicated GPU infrastructure through bare metal servers based on NVIDIA’s reference cloud architecture, utilizing advanced hardware such as NVIDIA H100, H200, and Blackwell units.
Key capabilities and functional benefits include:
- Unified API: Simplified access to a library of Large Language Models (LLMs) and multimodal models, including options like DeepSeek, MiniMax, and Gemini.
- Optimized Performance: The ability to achieve up to 5x faster inference and significantly higher throughput compared to general-purpose clouds.
- RDMA-ready Networking: Ensures minimal latency and stable performance across multi-node clusters, ideal for large-scale training and inference.
- Configuration Flexibility: Supports everything from serverless endpoints to root access and custom stacks on dedicated clusters.
- Multi-tenant Isolation: Ensures predictable and secure performance, preventing interference between different workloads on the same physical server or host.
GMI Cloud is aimed at development teams and companies that need to move AI prototypes into real-world production environments. It is especially valuable for real-time video generation applications, audio systems, and voice cloning, as well as for developing foundation models that require low inference latency and high resilience. By centralizing compute and orchestration on an optimized platform, users can efficiently scale their generative AI operations, reducing operational costs and accelerating technological iteration cycles.
GMI Cloud features and use cases
How to use GMI Cloud
GMI Cloud FAQ
What is GMI Cloud and what services does it offer?
GMI Cloud is a unified AI infrastructure platform that provides computing, inference, and agent solutions optimized for scaling artificial intelligence projects in production.
Which GPU models are available on GMI Cloud?
We currently offer access to NVIDIA H100 and H200 GPUs for immediate use, as well as the option to place reservations for the upcoming NVIDIA Blackwell platform.
What is the hourly cost for GPU usage?
The rate for the NVIDIA H100 is $2.00 per hour of use, while the NVIDIA H200 model is priced at $2.60 per hour.
How does GMI Cloud handle inference scaling?
Inference is serverless by default and allows for automatic scaling to zero during periods of inactivity, eliminating unnecessary downtime costs.
What types of AI models can be run on the platform?
You can run Large Language Models (LLMs), image, video, and audio generation systems, and any multimodal workloads through a unified API.
What performance advantages does GMI Cloud offer compared to other providers?
Our infrastructure achieves five times faster inference and twice the scaling speed during peak demand, reducing operating costs by 30%.
Does GMI Cloud offer dedicated infrastructure options?
Yes, we offer bare-metal servers with root access and dedicated GPU clusters for workloads that require full control and predictable performance.
Which specific models can be found in the GMI Cloud library?
We provide access to leading models such as MiniMax-M3, DeepSeek-V4, Gemini-3.6-Flash, and various voice cloning and image generation tools.
Is GMI Cloud an official NVIDIA partner?
Yes, we are an NVIDIA Preferred Partner, and our cloud architecture is validated against their reference designs to ensure maximum reliability and scale.
GMI Cloud pricing and plans
Serverless Inference: Pay-as-you-go pricing with no idle costs.
Auto-scaling to zero when there is no load.
Integrated batching.
Latency-optimized job scheduling.
Multi-tenant isolation to ensure predictable performance.
Access to production-ready LLM and multimodal model APIs.
NVIDIA H100: $2.00/hour per GPU.
Dedicated GPU infrastructure (bare metal).
Ideal for inference and training tasks requiring high memory bandwidth.
Support for large-scale models.
Root access and custom stacks.
NVIDIA H200: $2.60/hour per GPU.
Optimized for large-scale training and inference.
High performance and guaranteed availability.
Infrastructure-level multi-node cluster orchestration.
NVIDIA Blackwell: Contact for pre-order availability.
Designed for massive deployments requiring peak performance.
Coming soon to the platform.
Model Library (API): Variable pricing per million tokens or per request.
MiniMax-M3: $0.24/M input tokens and $0.96/M output tokens.
DeepSeek-V4-Flash-0731: $0.286/M input tokens and $0.858/M output tokens.
Gpt-6.1-Sol: $2.00/M input tokens and $10.00/M output tokens.
Gemini-3.6-Flash: $1.50/M input tokens and $7.50/M output tokens.
Audio Models (Minimax): Between $0.06 and $0.15 per request depending on the version (Turbo/HD).
Image Models (Hunyuan/Hy-Image): Between $0.024 and $0.08 per request.
GMI Cloud Screenshots
GMI Cloud alternatives
localscreenshot
localscreenshot is a screenshot API and MCP server for AI agents, returning clean captures of any web page on phone or desktop from 227 countries.
Nuclr Commander
Workspace for running multiple AI agents in parallel with a file manager. Supports local or external models and remote mobile monitoring.
SpeakCrate
Open-source API for local, private speech synthesis. Generate multilingual audio on your own servers with OpenAI standard compatibility.