Share
Infrastructure to deploy, monitor, and train AI models. Optimize LLM performance in production with real-time evaluation and observability tools.
What is Inference?
Inference is an advanced infrastructure platform designed specifically for engineering teams developing AI-native applications. Its primary function is to facilitate the deployment, monitoring, and training of large language models (LLMs) that are open-source, custom, or fine-tuned to operate at scale. This tool enables organizations to migrate from closed-source providers to an optimized infrastructure that drastically reduces latency and operational costs without sacrificing quality.
Model deployment capabilities are one of its fundamental pillars. Inference offers a high-performance hosting environment that allows for running models such as GLM-5, MiniMax, or GPT-OSS on public, private, or hybrid cloud infrastructures. Thanks to its technical architecture, teams can achieve 99.99% availability and significantly reduce production response times, ensuring that any server or machine processing requests maintains constant and reliable inference speeds.
To ensure optimal performance, the tool integrates a production-grade LLM observability system. This functionality enables tracking of every request, analyzing prompts, tool calls, and responses in real-time. Developers can monitor critical metrics such as p90 latency, token usage, and error rates. Key capabilities include:
- Production monitoring: Detailed tracking of every request path to identify provider behaviors and usage patterns.
- Automated fine-tuning: Workflows for fine-tuning custom models in minutes, adapting them to domain-specific tasks.
- Continuous evaluation: Comparing model variants against real production traces to detect regressions before deployment.
- Data curation: Automatically transforming production traces into high-signal training datasets.
Inference stands out for its focus on a private data flywheel, allowing the model to improve with every cycle by learning from end-user data. This is particularly useful for data extraction, classification, and AI agent applications that require higher precision than generic models.
Security is another key aspect, as the platform is SOC 2 Type II certified, guaranteeing full control and operational oversight across the entire tech stack. This makes it a robust solution for companies that need to scale their inference infrastructure while maintaining data privacy and sovereignty. With a focus on efficiency, it helps product teams achieve frontier-level performance with lower compute consumption.
Inference features and use cases
How to use Inference
Inference FAQ
What exactly is the Inference platform, and what is it used for?
It is an inference infrastructure designed for AI-focused teams, enabling the deployment, monitoring, and training of open-source models at scale with optimized performance.
Can I migrate my workloads from OpenAI or Anthropic to Inference?
Yes, the tool allows you to easily switch from proprietary providers to open-source models running on infrastructure specifically optimized for each workload.
How does Inference’s AutoEvals feature help in finding the right model?
This feature allows for the continuous evaluation of models by comparing them against real production traces to measure quality, cost, and latency before final deployment.
What availability guarantees does Inference offer for model deployment?
The platform guarantees 99.99% uptime to ensure that models remain operational in mission-critical production environments.
Is it possible to fine-tune custom models on Inference?
Yes, you can fine-tune frontier-level language models in just minutes using automated workflows based on your own production data.
Does Inference comply with security standards for data handling?
The platform is SOC 2 Type II certified, ensuring full control and strict operational oversight of data and models across the entire infrastructure.
What pricing plans does Inference offer for new users?
We offer a free pay-as-you-go plan to get you started, a Growth plan at $250 per month for teams with production workloads, and custom Enterprise options.
What kind of observability does Inference provide for deployed models?
The tool allows you to track every request to view prompts and responses, while also monitoring latency and usage patterns as traffic scales.
Inference pricing and plans
Pay as you go
$0 + usage
1 million Gateway requests included.
1 million tracing spans per month.
14-day data retention.
1 seat.
30 req/min rate limit.
Growth
$250 per month
$50 one-time signup credit.
50 million Gateway requests per month.
50 million tracing spans per month.
Unlimited data retention.
Unlimited seats.
250 req/min rate limit.
Enterprise
Contact Sales
Custom contracts and committed-use pricing.
Dedicated infrastructure and custom deployment limits.
Direct support channel with the engineering team.
Custom models trained for specific workloads.
In addition to subscription plans, deploying models on B200 instances (such as Kimi K2.5, MiniMax-M2.5, GLM-5, or GPT-OSS 120B) costs $9.98 per hour.
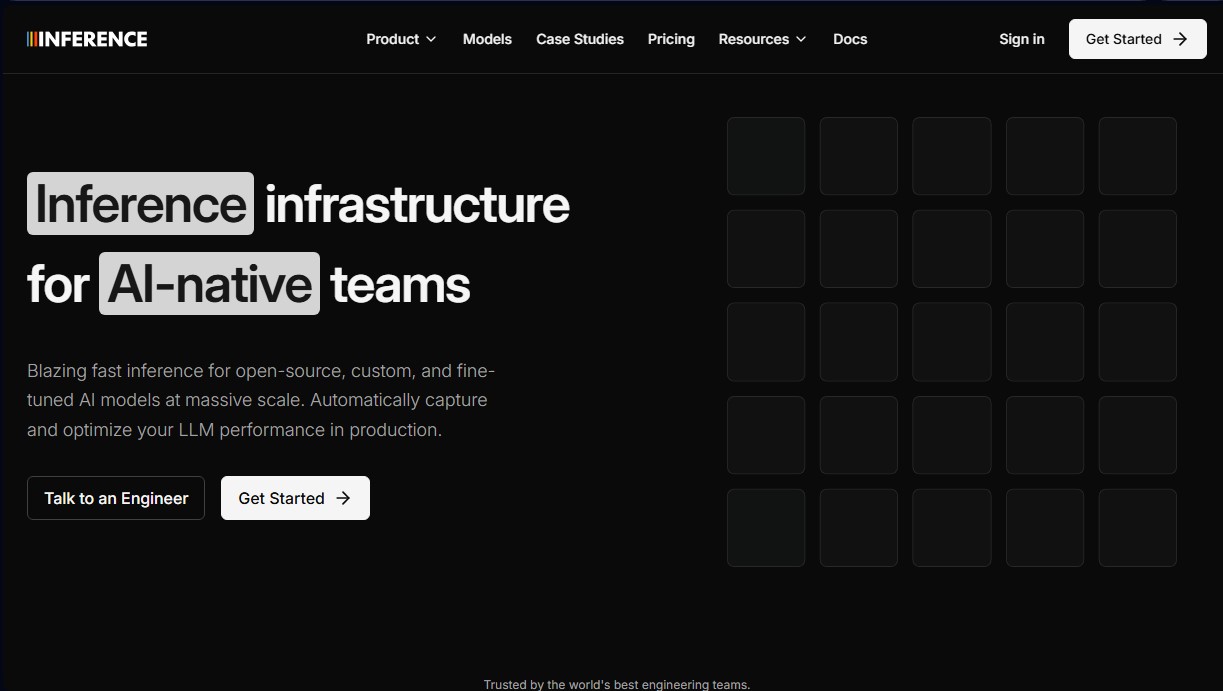
Inference Screenshots
Inference alternatives
Nuclr Commander
Workspace for running multiple AI agents in parallel with a file manager. Supports local or external models and remote mobile monitoring.
SpeakCrate
Open-source API for local, private speech synthesis. Generate multilingual audio on your own servers with OpenAI standard compatibility.
Agent-Native
Agent-Native is an open-source TypeScript framework for building AI agents with a proper UI, where the agent and the interface share actions, data and state.