Share
What is Liquid Inference?
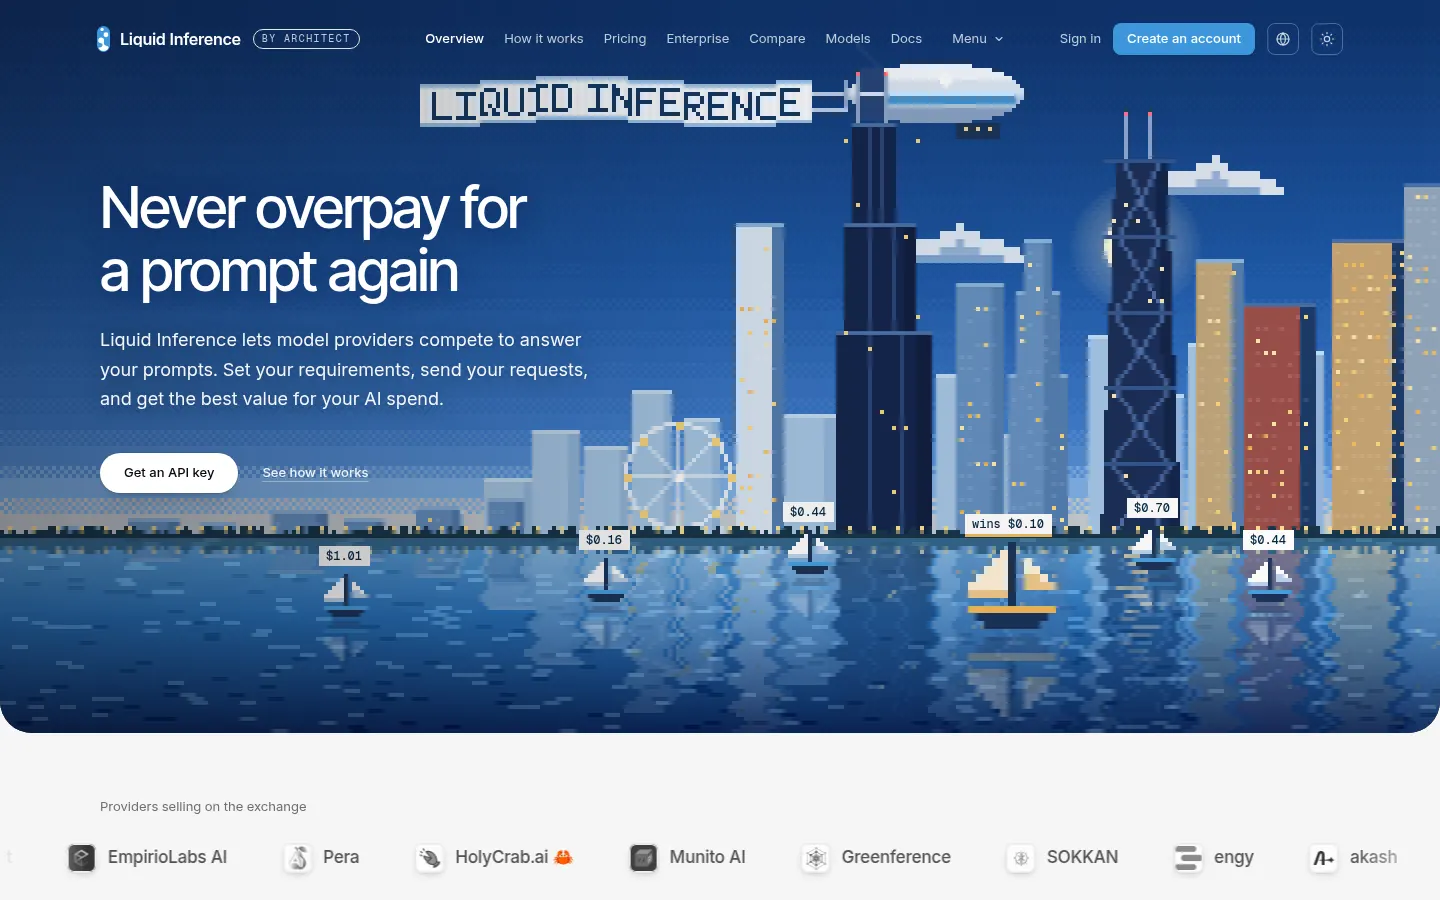
Liquid Inference is an AI tool that works as an auction exchange for LLM inference. Model providers compete to answer each of your requests: you set your requirements, send the request and the best offer wins the job, so you get the most value out of your AI spend.
What is Liquid Inference used for?
It lets you stop overpaying for prompts without rewriting your code. Each provider posts a per-token rate for every model it serves, and every request triggers an instant auction. The winning offer is capped before the model starts, so a job never exceeds that cap and the unused part goes back to your balance. Offers move with supply and demand: providers drop them when they have spare capacity.
How does Liquid Inference work?
Most OpenAI or Anthropic code changes in two places: the base URL and the API key. It works with clients and AI coding tools that speak those APIs, such as GitHub Copilot CLI. You can restrict requests to zero-retention providers, check independent benchmarks and public rate history, and find the best model for your cap. The Auto Router picks a model by published score within a limit, and reservations give you a monthly token pool from one provider.
Who is Liquid Inference for?
- Developers calling LLMs from their apps or agents.
- High-volume teams looking to cut AI spend.
- Coding-agent users running open models.
- Providers with GPU capacity who want to sell inference.
Liquid Inference pros and cons
It is transparent: every job has a receipt showing the winning offer and usage, the exchange does not store request or answer text, and if a provider fails before output the next offer is tried. It also has a CLI and an MCP server. On the downside, only model names listed on the exchange work, and quality can vary between providers.
Liquid Inference features and use cases
How to use Liquid Inference
Liquid Inference FAQ
What is Liquid Inference?
Liquid Inference is an exchange where AI model providers compete in an auction to answer each request at the best rate.
Is Liquid Inference free?
No, it is pay as you go plus an exchange fee, though new workspaces get a starting credit with no card; details are in the pricing section.
What do I change in my code?
For most OpenAI or Anthropic code, the base URL and API key, using model names the exchange lists.
Can a request cost more than I expect?
No, a cap is set before the first token and the job never exceeds it.
Does it keep my prompts?
It does not store request or answer text, except prompts you save in a workload; you can restrict requests to zero-retention providers.
What if a provider fails?
Before any output the exchange tries the next offer; once output starts it does not switch providers.
Does Liquid Inference have an API?
Yes, it is an OpenAI- and Anthropic-compatible API, with a CLI and MCP server too.
Does Liquid Inference work in Spanish?
The site is in English; the models it serves can take and answer Spanish prompts depending on each model.
Can I sell inference on Liquid Inference?
Yes, providers register their deployments, set their rate and get paid for the tokens they serve.
What are the alternatives to Liquid Inference?
In our directory you can compare it with OpenRouter for unified access to many models, or Groq for fast open-model inference.
Liquid Inference pricing and plans
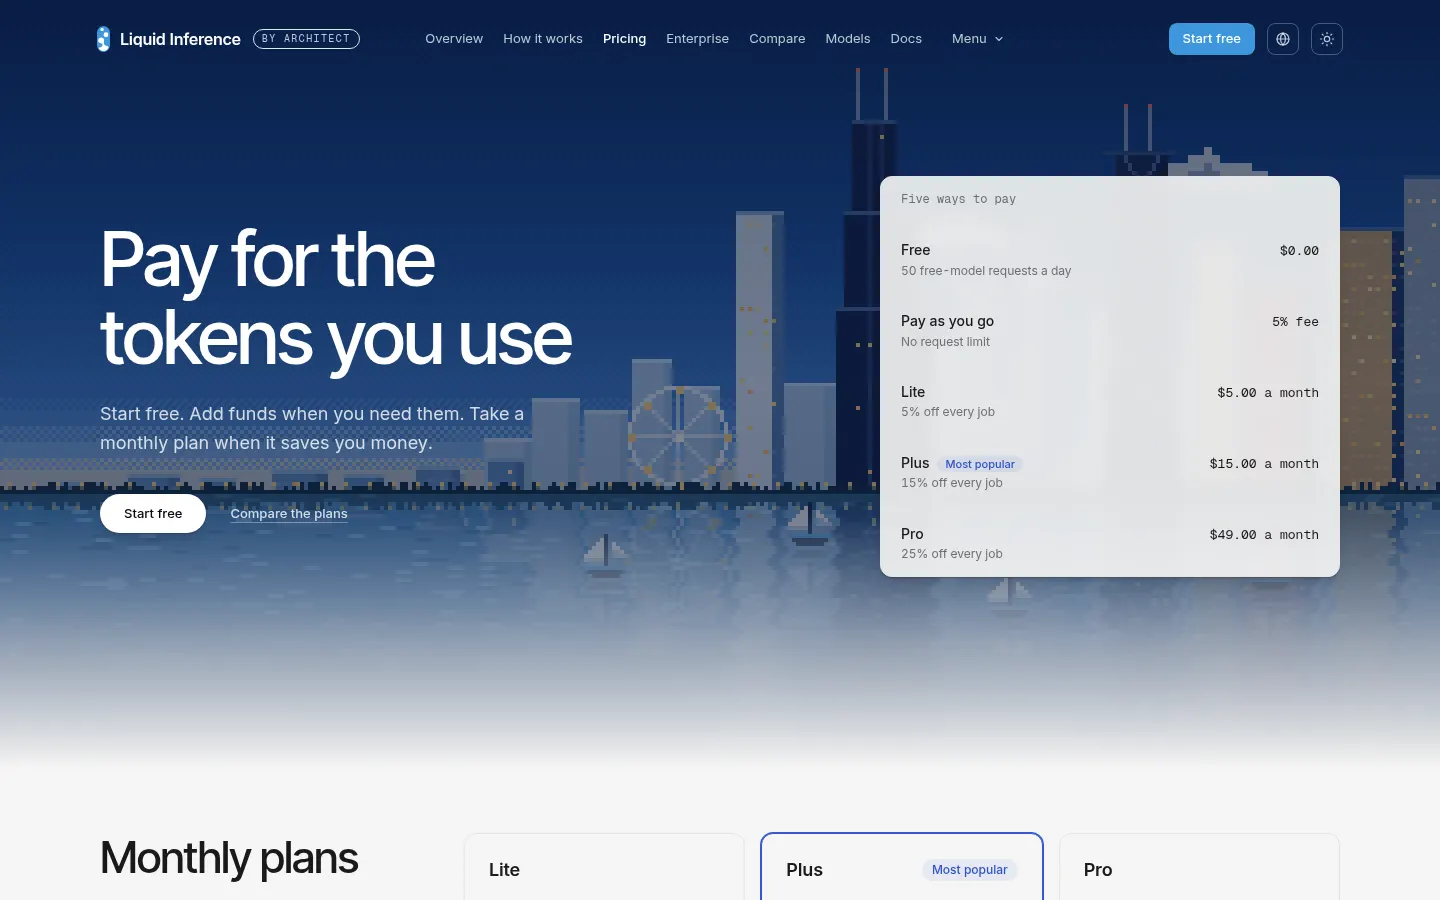
Prices in US dollars (USD) from the official site, pay as you go. Checked on: 17/11/2026.
You pay for each job's tokens at the winning provider's rate (it varies by model and by minute) plus the exchange fee: the larger of 5% of the provider's charge and a floor of 1 cent per million tokens. A job that fails before any output pays no fee.
- New workspaces get a starting credit to try it with no card.
- Reservations: a monthly token pool from one provider at a quoted fixed fee.
- Providers pay no listing or transaction fees.
Liquid Inference Screenshots
Liquid Inference user reviews
Write a review
Checking your session...
Liquid Inference Reviews
Loading reviews...