Share
Unified inference platform to optimize and run AI models across GPUs, CPUs, and ASICs. Maximize performance and lower costs with seamless hardware portability.
What is Modular?
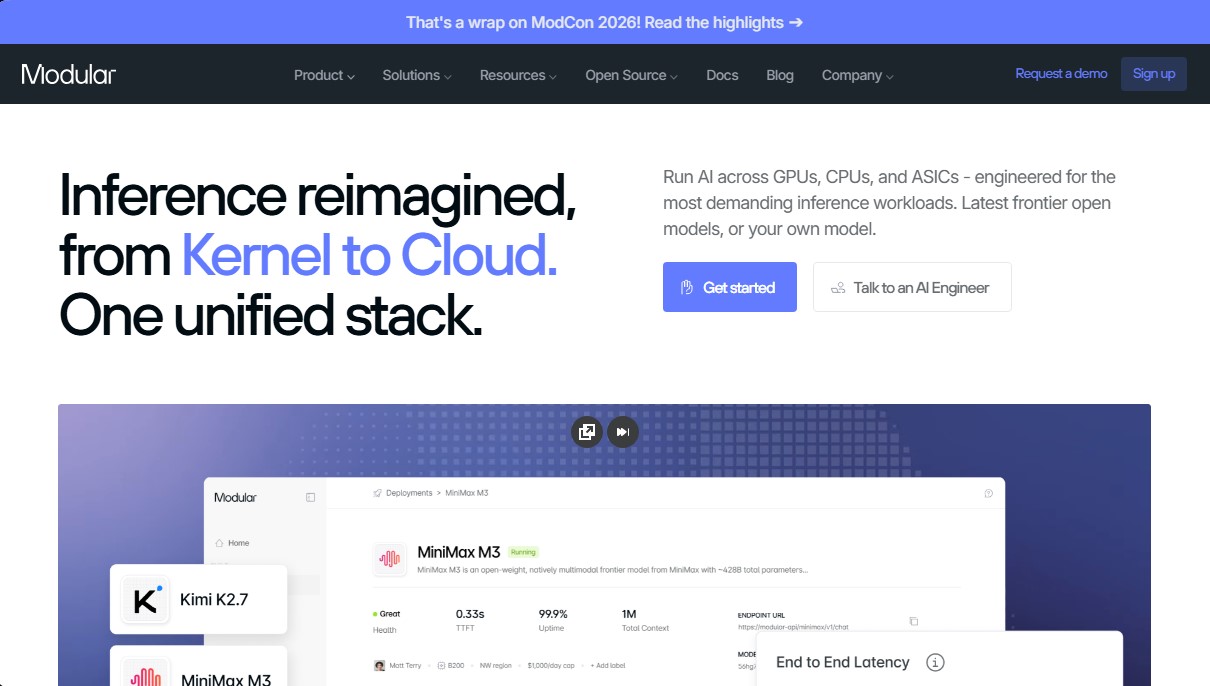
Modular is a unified AI inference platform designed to optimize model performance and portability across diverse computing environments. This solution integrates a complete tech stack spanning from the kernel to the API endpoint, enabling the efficient execution of high-demand artificial intelligence workloads. Its primary goal is to eliminate AI infrastructure fragmentation by offering a cohesive system that works across data centers, local devices, and personal computers.
The tool’s architecture is built on two fundamental pillars: the MAX inference engine and the Mojo programming language. Mojo is presented as a high-performance evolution of Python, allowing developers to write simple code that compiles to take full advantage of modern accelerators. Meanwhile, Modular’s compiler technology automatically generates optimized kernels for different hardware architectures, ensuring true vendor independence and preventing lock-in with a single chip manufacturer.
One of Modular’s greatest advantages is its ability to run the same code and models across a wide variety of processors without the need for costly rewrites. The system supports more than 15 GPU, CPU, and ASIC architectures, including:
- NVIDIA and AMD (such as the MI355X series).
- Apple Silicon (M1, M2, and M3 chips) and ARM architectures.
- Specialized hardware like AWS Trainium, Google TPU, and Qualcomm solutions.
- Intel processors and standard x86 architectures.
The platform offers deployment flexibility to meet the security and scalability needs of every technical team. Modular Cloud provides managed endpoints (shared or dedicated) with low latency, while the Your Cloud (BYOC) option allows for execution within the client’s own VPC to maintain data privacy. There is also a Self-Hosted version via containers for total infrastructure control.
In practical terms, Modular stands out for significantly reducing Time to First Token (TTFT), bringing it below 500ms in conversational applications. It is an essential tool for AI engineers and companies looking to implement:
- AI agents and programming copilots with instant responsiveness.
- High-speed image generation models and visual workflows.
- Text-to-audio systems with real-time natural speech synthesis.
- Deployment of Large Language Models (LLMs) such as DeepSeek R1, Llama, or MiniMax M3.
Thanks to its focus on full-stack optimization, the tool delivers up to 2x additional performance and considerable operational cost savings by maximizing the utilization of available hardware. It is a robust solution for those needing to scale AI applications from the prototype phase to mass production without sacrificing technical control.
Modular features and use cases
How to use Modular
Modular FAQ
What exactly is the Modular platform?
Modular is a unified AI inference infrastructure that allows you to run models on various hardware architectures with optimized performance.
What kind of hardware can I run my models on with Modular?
The platform is compatible with a wide range of processors, including NVIDIA and AMD GPUs, as well as CPUs and ASICs from Qualcomm, Apple, Intel, and AWS.
What advantages does the Mojo programming language offer within the Modular ecosystem?
Mojo is a language designed for AI development that combines Python's syntax with C-level performance, allowing you to write high-speed custom kernels.
What deployment options are available on Modular?
You can choose between using Modular’s managed cloud, deploying to your own cloud via VPC, or using the self-hosted version in your own containers.
How does Modular's pricing model work?
Costs vary depending on the deployment method, offering pay-per-million-tokens for shared endpoints or per-minute rates for dedicated GPUs.
What performance improvements can I expect when using Modular?
Modular offers a significant reduction in latency with response times under 500 milliseconds and cost savings of up to 70 percent.
Is Modular compatible with the most popular AI models on the market?
Yes, it supports the latest open-source models like DeepSeek and Llama, fine-tuned variants, or even your own custom models.
Does Modular offer specialized technical support for enterprises?
Yes, paid editions include support from expert engineers who help optimize workloads and assist with infrastructure migration.
Modular pricing and plans
Self-Hosted (Community Edition): Free.
Containerized installation (under 700MB).
Includes MAX and Mojo for execution on your own infrastructure.
Community support via Discord and GitHub.
Compatible with various GPU and CPU architectures.
Modular Community License.
Modular Cloud (Shared Endpoints): Pay-as-you-go based on token consumption. Try shared endpoints for free initially.
No infrastructure management or long-term commitments.
Access to frontier models (DeepSeek V4, Llama, Qwen, etc.) via OpenAI-compatible API.
Variable pricing per million tokens based on the model (e.g., DeepSeek V4: 1,74 $ input / 3,48 $ output).
Integrated usage metrics and observability.
Modular Cloud (Dedicated Endpoints): Pay-per-minute or hourly GPU pricing.
Reserved GPUs from various providers for consistent performance.
State-of-the-art (SOTA) inference optimized for demanding workloads.
Includes forward-deployed engineers for deployment tuning and optimization.
Secure environment fully managed by Modular.
Bring Your Own Cloud (BYOC): Pay-per-minute for reserved GPU capacity.
Deployment in the customer's private cloud (VPC) or on-premises servers.
Data always remains within the user's infrastructure for maximum privacy.
Specific optimization of customer pipelines and workloads.
Custom APIs and dedicated engineers for technical support and migration.
Enterprise: Custom pricing via consultation with the sales team.
Full data control and hybrid deployment options.
Runs on any compatible hardware (NVIDIA, AMD, AWS Trainium, Google TPU, etc.).
Ability to create custom Mojo kernels for novel model architectures.
Advanced engineering support and custom contracts.
Modular Screenshots
Modular user reviews
Write a review
Checking your session...
Modular Reviews
Loading reviews...
Modular alternatives
Together Link
Connect coding agents to open models to cut costs. Keep your existing tools and settings while optimizing token usage in every session.
Optimus by Iacon Autonomics
Autonomous researcher designing experiments and evaluating algorithms to train AI models. Automates improvement cycles for LLMs, robotics, and various complex systems.
Nuclr Commander
Workspace for running multiple AI agents in parallel with a file manager. Supports local or external models and remote mobile monitoring.